AI Gets 57% of Financial Answers Wrong — Error Rate Reaches 88% on Complex Questions
 ·
20.09.2026 19:26
·
3 min read
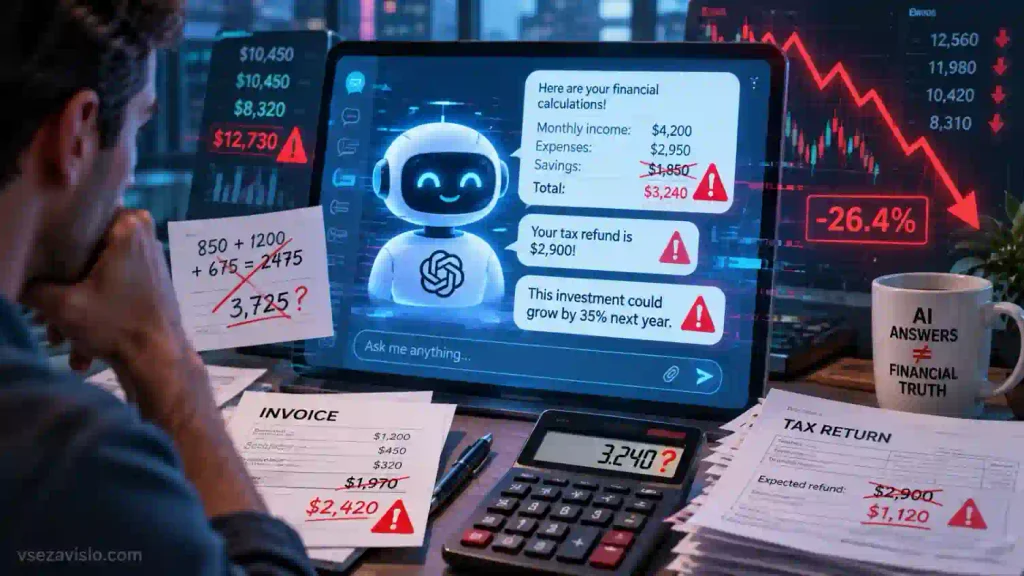
Popular AI models provide incorrect answers to financial queries 57% of the time on average, according to a study by UK fintech company Saturn, which evaluated 18 models including ChatGPT, Claude, Gemini, Copilot, and Grok.
Researchers compiled 121 personal finance questions spanning taxes, pensions, debt, savings, mortgages, and other topics. Each prompt was submitted to the models up to five times to evaluate both accuracy and consistency, yielding more than 10,000 analyzed responses.
According to the Saturn report, only around 43% of the answers were correct. The failure rate climbed significantly on complex questions, reaching an average of 88%, with some individual models failing 99% of the most demanding tasks.
Errors Went Beyond Simple Calculation Mistakes
The issues were not confined to basic math. Models routinely missed essential risk warnings, failed to reflect changes in tax law, and in some cases cited nonexistent rules.
In one example, an inaccurate response regarding pension taxation could have left a user facing an unexpected £17,500 tax bill from HMRC. In other instances, AI suggested debt repayment strategies that ignored high-priority obligations such as rent or council tax.
Saturn classified an answer as incorrect not only for blatant factual errors, but also when a model omitted critical details or mandatory disclosures. As a result, the 57% figure reflects a broader failure to meet evaluation criteria rather than purely hallucinated answers.
Even the Top-Performing Model Failed Nearly 4 in 10 Times
Performance varied widely across models. Free versions failed 63% of the time on average, while paid tiers averaged a 49% error rate.
Claude Haiku 4.5 posted the lowest score among the tested systems, failing in 82% of its answers. Gemini 3.1 Pro recorded a 73% error rate, Grok 4.5 landed at 59%, and ChatGPT 5.6 Luna missed the mark in 58% of tests.
Claude Opus 5 in reasoning mode delivered the strongest performance, though it still fell short in approximately 39% of cases.
The findings come with notable caveats. The study was conducted by Saturn itself, a fintech firm with a vested interest in the regulation of AI financial advice. Because the company established its own methodology and grading criteria, the study does not represent an independent academic benchmark.
Still, the conclusion aligns with a broader issue facing modern language models: they deliver financial guidance with high confidence even when underlying calculations, regulatory rules, or baseline assumptions are flawed. For critical decisions involving taxes, debt, investments, or retirement, AI guidance still requires verification against official sources or consultation with a qualified professional.